Running AI agents on a schedule: three pitfalls, starting with "exit 0 does not mean success"
Putting an AI agent on a schedule is the obvious next step: organize data every morning, generate the report, run the digest — wake up and read the results.
I did this on macOS with launchd. The script passed every manual run in the terminal, a hundred out of a hundred. On its first scheduled night, it died.
Worse: I only found out the next morning — because it died quietly.
Pitfall one: the scheduled environment cannot touch directories you assume it can
macOS has a privacy layer called TCC: directories like ~/Documents, ~/Desktop, and ~/Downloads require per-app user consent to read. You never notice in a terminal because your terminal app was granted access long ago.
A process launched directly by launchd inherits no such grant. When it reads a project directory under ~/Documents, it gets EPERM — or the more confusing behavior: it simply hangs.
For AI agents this is especially lethal, because headless agent CLIs are working-directory-centric. Put the working directory under a protected path and the entire agent is soaking in permission errors.
| Environment | Reading ~/Documents | Why |
|---|---|---|
| Manual, in a terminal | Works | The terminal app holds a TCC grant; child processes inherit it |
| Scheduled, under launchd | EPERM or hang | A launchd process has no grant to inherit |
The fix is not to grant launchd access (possible, but brittle — grants bind to a binary's hash and silently vanish when the tool updates). The fix is to route around the problem entirely:
Scheduled jobs put their working directory and every file they touch under a neutral path such as ~/.local/share/<job-name>/. If a result genuinely needs to appear in Documents, symlink it there — interactive use through a symlink is completely transparent.
Related: the scheduled environment does not load your shell profile either. Your PATH does not contain your tools. Export it explicitly inside the script; never assume.
Pitfall two: non-TTY stdin makes CLIs wait forever
The second pitfall has the strangest symptom: the agent CLI starts under the schedule and then does nothing. No error, no output, no exit — not even a session file.
The cause is stdin. Interactively, stdin is your keyboard. Mine was codex exec. In a non-interactive background shell with no stdin given, it kept waiting for EOF. Adding < /dev/null fixed it. Docs do not always say what stdin a scheduler gives by default. When unsure, set it yourself.
# Wrong: no stdin given; codex exec waits for EOF in a background shell
codex exec "organize today's data" > log 2>&1

# Right: give it /dev/null, so stdin hits EOF at once
codex exec "organize today's data" < /dev/null > log 2>&1
The general rule: any CLI may change behavior without a TTY — reading stdin, disabling color, demanding interactive confirmation. Before running anything in the background, decide what its stdin is; when unsure, give it /dev/null.
Same for output: write to a file and parse afterwards rather than piping — SIGPIPE from a downstream exit is a whole other nest of problems.
Pitfall three: exit codes lie
The third pitfall is the most expensive, because its failure mode is "everything looks fine".
My job script originally judged success by exit code: tool returns 0, mark it green. Until I noticed several consecutive days of "success" during which the output file had not gained a single character. The tool was headless Claude Code (claude -p). macOS TCC blocked its file reads, so it got EPERM and wrote the error into its output. The run itself still completed, so it returned exit 0.
For ordinary programs the exit code is a reliable contract. For AI agents — tools that swallow errors internally and keep trying — it often means only "the process ended normally", not "the task succeeded".
So every scheduled job now carries a four-piece kit, built on one principle: when it breaks, it must be impossible to miss.
| # | Practice | Defends against |
|---|---|---|
| 1 | Verify the result itself: check the output file for today's date and expected content — never the exit code | exit 0 with actual failure |
| 2 | Watchdog: cap the child process's runtime, kill on timeout (macOS has no timeout command; poll with kill -0) | Hangs that never end and never report |
| 3 | Failure notifies actively: system notification + status file + a loud FAILED in the log + nonzero exit | Failing quietly for days |
| 4 | End-to-end verification through a real scheduled trigger, not just manual runs | Every environment difference between manual and scheduled |
Point four deserves expansion, because it is exactly what the first two pitfalls teach: passing manually proves nothing about the schedule. On macOS you can force one genuine scheduled execution:
launchctl kickstart gui/$(id -u)/<your-job-label>The environment that command produces is the one your job actually faces every night. One end-to-end pass through it before going live is worth more than ten manual runs.
Example: how the Claude Code docs define "failed"
Claude Code is an AI agent tool from Anthropic that can run in a terminal. One page of its official docs covers non-interactive mode, including exit codes (read 2026-11-05).
The docs say Claude Code exits with code 0 on success and a non-zero code when the run fails. Scripts can branch on that exit status.
The same passage separates two kinds of failure. With an invalid flag, the error goes to stderr before the run starts. When a failure happens inside the run, such as missing authentication, the failure is printed as the result on stdout.
The SDK docs also define a result message. Its subtype can be success, or an error type such as error_max_turns or error_during_execution. There is also an is_error field.
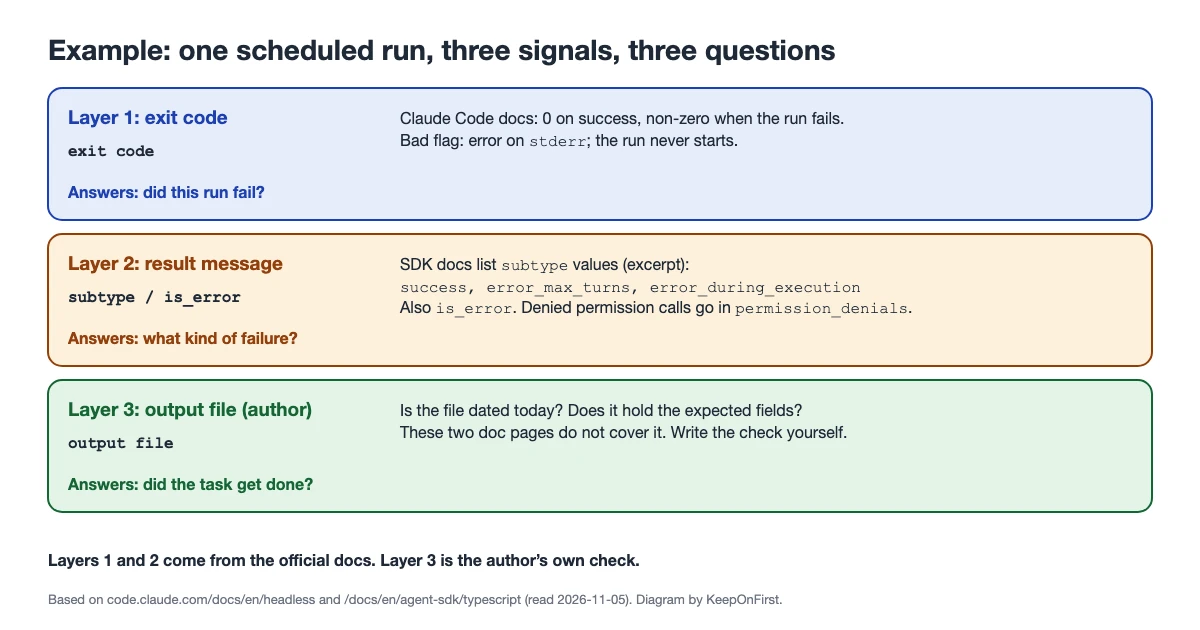
Both are useful signals, and I check both. But they answer narrower questions: did this run fail, and what kind of failure was it?
A scheduled job needs a different answer: did today’s output file get the expected content?
The two can disagree. Pitfall three was such a case. macOS blocked a file read, Claude Code wrote EPERM into its output, the run completed, and the exit code was 0.
This does not conflict with the docs. A failed file read is not a failed run.
The docs describe a related case. When Claude Code’s own permission system denies a tool call, the run continues. With stream-json output, the final result message lists those calls in permission_denials.
A macOS block is not part of that permission system. The docs do not say whether it appears in permission_denials.
So item 1 of the kit stays as the last check: inspect the output file itself.
The diagnostic habit: suspect the environment before the logic
The three pitfalls compress into one sentence: if it passes interactively and fails on the schedule, suspect environment differences first — TCC, PATH, stdin, keychain, HOME — not your program logic.
The effective isolation move is a disposable probe job that tests minimal actions inside the real scheduling context: can it read that directory, can the tool execute at all. Bisect from there — far faster than staring at your own code and guessing.
The hard part of unattended automation was never the automation. It is accepting one fact: that environment is not your shell. Permissions, input, and failure reporting all have to be rethought under its rules.