OKF vs RAG vs vector databases: what differs, and when to use each
Headlines like "Beyond RAG: OKF is replacing the vector database" are compelling, but they also blur the boundary between three things that live at different layers.
If you are not sure what OKF is yet, start with the first article in this series. Here I go straight at the question people actually get stuck on: how are these three different, and when do I use which?
Start here: Will Google OKF replace RAG and vector databases?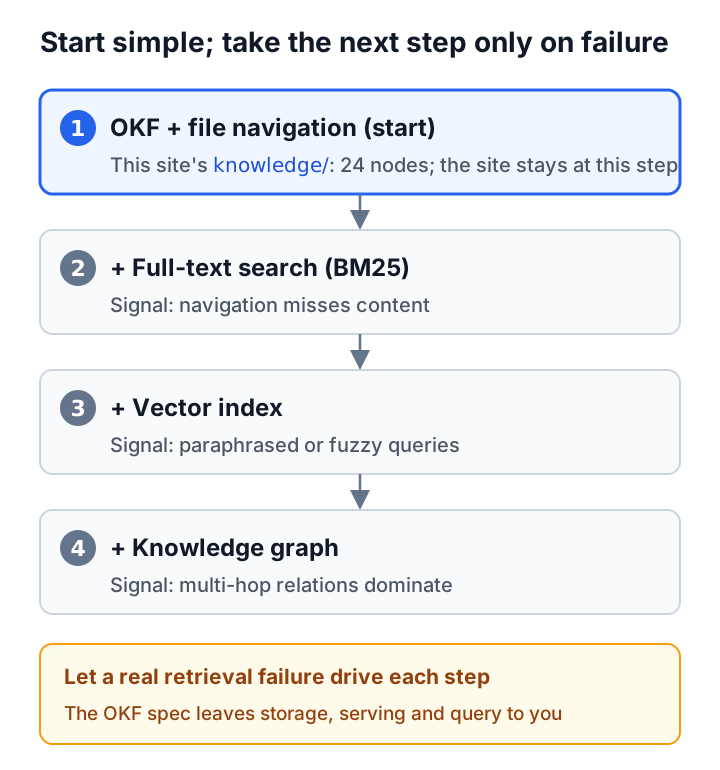
Put the three back in their proper layers
A simple way to remember it: OKF answers "what should knowledge look like," RAG answers "how to fetch external knowledge and generate," and a vector database answers "how to store vectors and do semantic similarity search." Each handles a different layer of the problem.
| OKF | RAG | Vector database | |
|---|---|---|---|
| What it is | A representation / interchange format | A retrieval workflow | A retrieval infrastructure |
| Which layer | How knowledge is authored, linked, versioned | How to fetch external knowledge before generation | How to store vectors and run similarity search |
| Best for | Curated, structured, repeatedly used knowledge | Dynamic search over large unstructured corpora | Paraphrased, fuzzy, semantic queries |
| Weakness | File navigation misses once it scales | Needs an index and synchronization | Chunking breaks structure; can retrieve stale chunks |
When OKF alone is enough
If the knowledge is curated, structured, and used repeatedly by an agent — metric definitions, APIs, deployment runbooks, architecture decisions — a directory of markdown plus file navigation is often enough. The corpus is small and the relationships are explicit, so an agent can inspect the path and context directly instead of relying only on embeddings, and you can diff and review it like code.
That is what I did in my own repo: one node each for architecture, decisions, and traps, so Claude and Codex do not re-crawl the whole repo every time. I report the experiment in the last article of this series.
Hands-on: turning a repo into an OKF bundle as agent memoryWhen you still need RAG or a vector database
Once knowledge becomes large, unstructured, and queried in paraphrase, file navigation cannot hold. You cannot ask an agent to traverse a hundred thousand support conversations or an entire document library. That is where the RAG workflow comes in; a vector database is a common retrieval infrastructure for it, using embeddings to find semantically similar content and handle fuzzy queries and synonyms.
OKF does not replace this layer. Its spec (now v0.2) explicitly says it does not prescribe storage, serving, or querying, and the official docs name a search index as one consumer. You can build a vector index on top of an OKF bundle.
How they work together
A workable arrangement is a division of labor: OKF is the source layer, keeping curated, structured, trusted knowledge in a readable, versionable format; vector/RAG is the retrieval layer, added when you need dynamic search over a large long tail. The agent does a structured lookup first (along OKF paths and links), then a semantic retrieval when needed. That is the subject of the later "OKF + RAG architecture" article in this series.
A practical decision rule
I would not dump the whole company into a vector database on day one. Start simple instead, and let observed retrieval failures decide whether to add complexity.
Start with OKF plus file navigation. Add full-text search (BM25) when navigation starts to miss content. Add a vector index when queries are frequently paraphrased and fuzzy. Consider a formal knowledge graph only when multi-hop relationships become the dominant problem. Let each step be driven by a real failure, not by reaching for the heaviest option first.
Example: this site stays at step 1, and the build checks only format
The knowledge/ folder in this site's repo stays at step 1. On 2026-11-04, knowledge/index.md listed 24 nodes in seven groups: entry, architecture, reference, data pipelines, gotchas, how-to and writing. An agent reads the index first, then picks nodes by their one-line descriptions. Section 8 of the spec says entries SHOULD include the description from the linked concept's frontmatter. Each entry on this site takes the form “* [title](path) - description”, and the build checks that format. The build checks only that a description exists; it does not compare it with the frontmatter. This site has no full-text index and no vector index.
An OKF gate runs at the end of the build (scripts/check-okf.mjs) and fails the build on any nonconforming bundle. It follows the three conformance conditions in §11 of the spec. First, each non-reserved .md file has parseable YAML frontmatter. Second, each frontmatter block has a non-empty type. Third, index.md and log.md follow the structure in §8 and §9.
The gate adds one site rule: relative links must point to files that exist. The spec, in §6.1, says the opposite for readers: “Consumers MUST tolerate broken links.” So this rule is a demand on the writer side, not a spec rule. The gate checks whether the knowledge is well formed, not whether an agent can find it.
This article does not measure the lookup miss rate on this site, so it does not claim that 24 nodes are always enough. The signal for step 2 is a recorded miss: an agent that cannot find the right node from its description. That is the time to add full-text search.
That makes "OKF vs RAG vs vector database" a misleading comparison. They operate at three different layers. The more useful question is: which layer is failing right now, and which one should I add?
Correction log
Updated on 2026-10-17. The v0.2 spec was first committed to GoogleCloudPlatform/knowledge-catalog on GitHub. The commit date is July 24, 2026 (UTC, commit 780fe9d). The text now says "spec (now v0.2)" instead of "v0.1 spec." v0.2 keeps the same non-goal for storage, serving, and query. The argument is unchanged. The spec and the official README are now listed as sources.