Diagnosing RAG errors: chunks, similarity, versions and scope
Suppose a system answers “How long should production orders be retained?” with 30 days. The retrieved passage really says 30 days, but it belongs to a test environment. The production rule is elsewhere. This is a hypothetical failure case, not customer data or a benchmark from this site.
Retrieval can return the same passage consistently and still produce the wrong answer. Separate distance calculation, applicability of the retrieved records, and whether the generated answer follows those records. Calling all three “probabilistic” obscures the diagnosis.
Similarity rank does not establish business correctness
The pgvector documentation distinguishes exact nearest-neighbor search from approximate search. Exact search finds the nearest items under the chosen distance; approximate search trades recall for speed. Perfect recall here concerns vector neighbors, not factual accuracy. With fixed vectors, data, distance and tie-breaking, exact ranking can be reproducible without identifying the currently applicable rule.
The previous article described vector retrieval broadly as probabilistic. The more useful distinction is that similarity and applicability can disagree. Record the query, candidate document IDs, scores, versions and filters. Check whether the correct document reached the candidate set before blaming generation.
Keep the context a passage needs
Long documents are often split for embedding, but a short document can be represented as a whole. Chunking is not mandatory for every vector search. Check whether each passage retains its heading, table headers, units and scope.
In the retention example, “orders: 30 days” is insufficient if “test environment” was left in a separate passage. Store section paths and environment metadata, or retrieve a parent section after finding a child. OKF can organize that source information, but an ingestion pipeline can still discard it. Changing file format does not repair indexing automatically.
Isolate the failure with a small dataset
The example below uses hand-assigned two-dimensional vectors to place a stale or wrong-environment record ahead of the applicable one. It demonstrates distance ranking versus filtering, not embedding quality, and calls no LLM. Save it as retrieval-check.mjs and run it with Node.js 22.
import assert from 'node:assert/strict';
const query = [1, 0];
const docs = [
  { id: 'test-v1', env: 'test', rev: 1, days: 30, v: [1, 0] },
  { id: 'prod-v1', env: 'prod', rev: 1, days: 90, v: [0.99, 0.01] },
  { id: 'prod-v2', env: 'prod', rev: 2, days: 180, v: [0.9, 0.1] },
];
const rank = rows => rows.map(d => ({ ...d,
  distance: Math.hypot(...d.v.map((x, i) => x - query[i]))
})).sort((a, b) => a.distance - b.distance || a.id.localeCompare(b.id));
const unfiltered = rank(docs)[0];
const scoped = rank(docs.filter(d => d.env === 'prod' && d.rev === 2))[0];
assert.equal(unfiltered.id, 'test-v1');
assert.equal(scoped.id, 'prod-v2');
console.log({ unfiltered: unfiltered.days, scoped: scoped.days });
// { unfiltered: 30, scoped: 180 }
Example: where the filter runs changes the result
The result above can be checked by hand. The query vector is (1, 0). The distance is 0 for test-v1, about 0.0141 for prod-v1, and about 0.1414 for prod-v2. Without a filter, test-v1 ranks first and the answer is 30 days. With only production revision 2 kept, prod-v2 remains and the answer is 180 days. The distances are correct. The candidate set contained a record that did not apply.
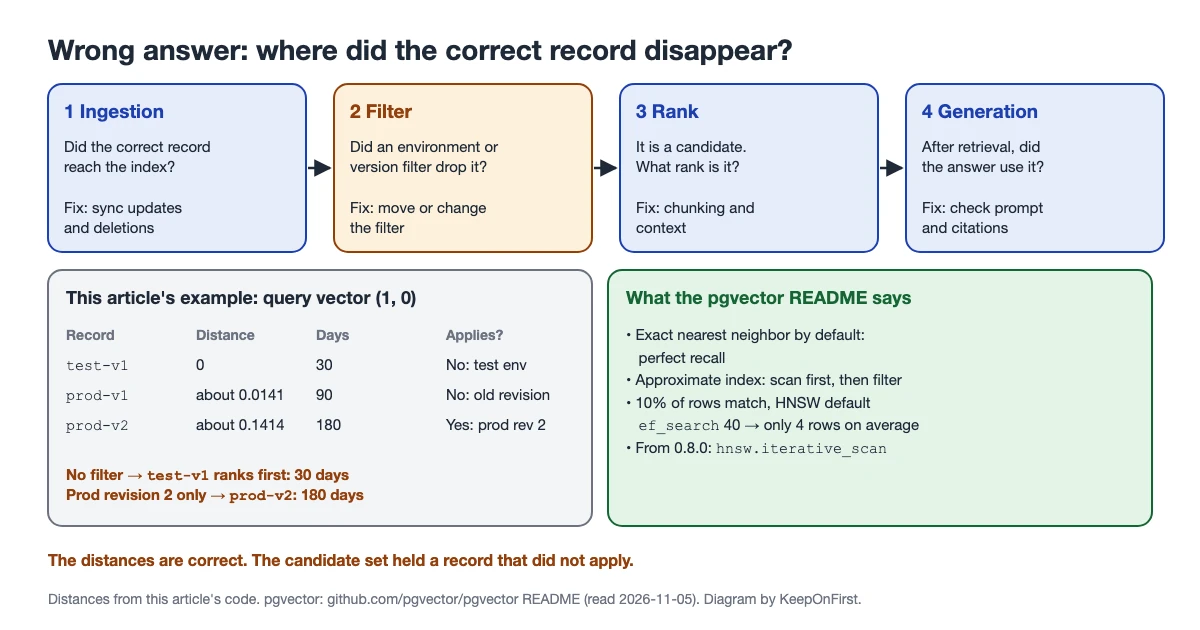
In a database, the position of the filter also matters. The pgvector README says that exact nearest-neighbor search is the default and provides perfect recall. Recall is the share of the relevant items that the search finds. With an approximate index, the filter is applied after the index is scanned.
hnsw.ef_search sets the size of the candidate list for an HNSW search. The default is 40. The README gives an example. If a condition matches 10% of rows, HNSW with the default hnsw.ef_search of 40 returns only 4 matching rows on average. Apply that to the retention case. Suppose production records are a small share. Then env = 'prod' can return fewer rows than requested. The correct record may be missing. This is an inference from the README sentence, not a measurement.
Starting with pgvector 0.8.0, iterative index scans automatically scan more of the index when results are short. For HNSW the setting is hnsw.iterative_scan, with strict_order or relaxed_order. Record the pgvector version before diagnosis, because versions before 0.8.0 do not have this setting.
Each wrong-answer record needs four fields at minimum. Was the correct record ingested? Did a filter exclude it? What was its rank? Did the answer use it after retrieval? Each field can be rerun with the same fixed questions.
Which layer OKF, RAG and vector databases each handle: “OKF vs RAG vs vector databases”.Updates must also retire old records
A source update does not prove that the index has caught up. Which embeddings need recomputation depends on whether the text, chunking method, embedding model or filter-only metadata changed. Deletions must reach the index too; simply adding a new version leaves conflicting rules available.
Build a new index version, check required records and fixed questions, then switch readers. Retain the previous version for rollback, but constrain each query to one active version. Record both source and index versions; an answer alone rarely tells you whether the failure involved source data, synchronization, ranking or generation.
Relationships need an explicit retrieval path
Similarity alone does not perform the join from an order to its plan and then to the applicable policy version. A workflow can query IDs, follow links or perform several retrieval steps and verify each. These methods can coexist with vector search; structured data is not inherently unsuitable for RAG.
For the next wrong answer, preserve the expected source ID and find the step where it disappeared. A missing record, a filter exclusion, a low rank and a model ignoring retrieved evidence require different fixes.
pgvector:Exact and approximate searchpgvector: Filteringpgvector: Iterative Index ScansOKF + RAG:索引契約 / Index contract