llms.txt vs AGENTS.md vs OKF: three kinds of "markdown for AI" that solve different problems
Lately there is a pile of "markdown for AI": llms.txt, AGENTS.md, CLAUDE.md, OKF. I happen to use all three across my site and repo, and the question I get most is the same one: "if I have one of these, do I still need the others?"
It is a bit like the question from my last piece — "is OKF replacing RAG?" It is confusing because it puts things from different layers side by side. The difference is not which is better, but who each one talks to.
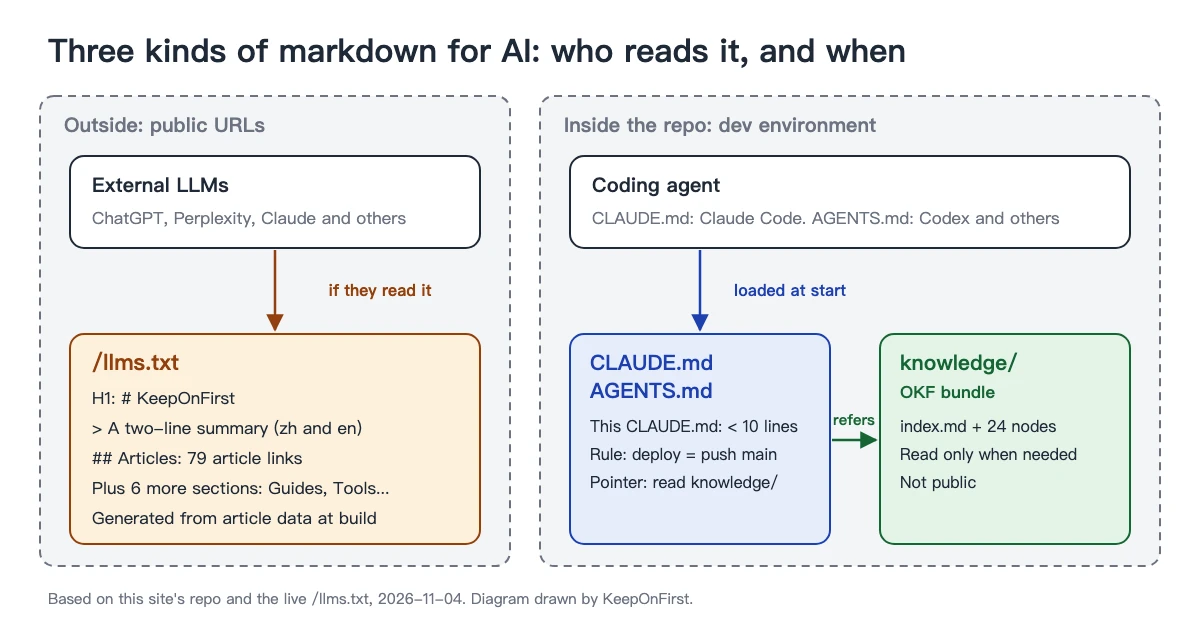
Here is the conclusion up front: llms.txt is for external LLMs reading your website, AGENTS.md/CLAUDE.md instruct the agent working inside your repo, and OKF is the structured knowledge that agent uses. Three layers, not three choices.
Same framing, previous piece: OKF vs RAG vs vector databaseThe real difference: who they talk to
To put them back in place, just ask three questions: who does it talk to, what does it contain, and when is it read?
| llms.txt | AGENTS.md / CLAUDE.md | OKF | |
|---|---|---|---|
| Who | External LLMs (reading your public site) | The coding agent working in your repo | An agent that needs knowledge |
| What | A curated map / index of the site | Behavior, rules, and pointers | The structured knowledge itself |
| Scope | One file, site level | One file, repo level | A directory of linked concepts |
| Contains | Key page links + blurbs | Conventions and where to look | Concepts, relationships, decisions |
| Read when | An LLM reads your site (if it reads the file) | The agent starts working | The agent needs a piece of knowledge |
llms.txt: presenting the site to LLMs
llms.txt is a markdown map at your site root (spec at llmstxt.org). It is written for external LLMs, to help them find key content and cite it correctly. It is still a proposal. As of November 2026, I could not find a public confirmation from the makers of ChatGPT, Perplexity or Claude that they use the file. Its audience is external models reading your site.
Jeremy Howard proposed the format on September 3, 2024. The only required part is an H1 with the name of the project or site. After it come a blockquote summary, optional notes, and H2 sections of links. Each link item is a markdown list item with a required [name](url); a note after a colon is optional. A section named "Optional" holds secondary links that a model can skip when it needs a shorter context.
The key point: it is not there to instruct your coding agent, and it is not a knowledge base. It is an outward-facing map. I added one to this site, generated from the article data so it updates automatically when I publish.
AGENTS.md / CLAUDE.md: instructions, not knowledge
AGENTS.md (read by Codex, Cursor, Gemini CLI and other tools) and CLAUDE.md (for Claude Code) are the entry files a coding agent loads by default when it enters your repo. They describe how to work: project conventions, common commands, rules, and where to find things. They do not hold knowledge; they hold behavior and pointers.
First-hand: I use them as the entry point that sends the agent to my OKF knowledge base — "read the relevant node in /knowledge before you work." Without this layer, the knowledge base just sits there and no one reads it.
The official site, agents.md, calls AGENTS.md "a simple, open format for guiding coding agents." It has no required fields; it is plain markdown. A monorepo can hold several. The one closest to the edited file takes precedence, so each subproject can have its own rules.
OKF: the knowledge itself
OKF is the thing being pointed to: structured, traversable, versionable knowledge — a directory of typed markdown, concepts linked into a graph. It answers "what should knowledge look like," not "how to behave" and not "how to be found from the outside."
Go deeper on OKF: Will Google OKF replace RAG and vector databases?A real example: what these three files say on this site
This is the state of this site on November 4, 2026. Start with the public file. The live /llms.txt opens with the H1 "# KeepOnFirst." Two blockquote lines follow: one summary in Chinese, one in English. Then come seven H2 sections: Articles, Guides, Tools, Apps, Signals, About and Knowledge. Articles lists 79 articles, one per line.
# KeepOnFirst
> (one-line summary in Chinese)
> (one-line summary in English)

## Articles
- [Article title](https://keeponfirst.com/article/<slug>): first sentences of the summary

## Guides
## Tools
## Apps
## Signals
## About
## Knowledge
Nobody writes this file by hand. The build script reads the indexable Chinese articles and writes one line per article. The title, URL and summary all come from the article data. Pages set to noindex do not appear, and game pages are left out.
Now the two inward files. This site's CLAUDE.md is under 10 lines and says three main things. First, read AGENTS.md. Second, the memory is in /knowledge. Third, deploying means pushing to main. AGENTS.md adds a few rules to know first, such as two gates at the end of the build that you must not bypass. Both stay short because their job is to point.
Key point: this repo's durable memory is the OKF bundle in /knowledge.
- Before work, read knowledge/index.md and visit the related nodes.
- After changes, update the affected nodes.
The knowledge/ folder is where the content lives. The frontmatter of index.md holds only okf_version. Below it, 24 nodes sit in groups such as architecture, reference, data pipelines, gotchas, how-to and writing. Each node has its own type, title and description. An agent reads the article data model node before it edits article data, and the deploy node before release. It never needs to read everything. This folder stays in the repo and is not public.
Write your own: How to write an OKF bundleChange something, update its layer
The most practical use of the layers is knowing which file a fact belongs in. The table shows three kinds of change this site has had.
| What happened | Where to edit | Why |
|---|---|---|
| A new article | Nothing by hand; llms.txt gains a line at the next build | It is generated from article data |
| The deploy process or a must-follow rule changed | Add a line to AGENTS.md/CLAUDE.md | The agent needs it at the start of every task |
| A new gotcha: the article source field has only label and url, no note | The matching node in knowledge/ | Only needed when that code is touched |
Put the third row in AGENTS.md and every task reads a detail it does not need. Putting it in llms.txt is worse: that file is for outside readers, and internal gotchas do not belong there.
How they compose (not replace each other)
In my actual setup the three coexist, each with its own job: AGENTS.md/CLAUDE.md is the entry instruction that points the agent to the OKF bundle; llms.txt goes the other way, outward, for LLMs that may read my site. The first two face inward, at the dev agent; llms.txt faces outward. None of them replaces another.
See it in practice: a repo as an OKF bundle for agent memorySo which one do you need?
Match to your need: a public site and you want to give LLMs a map → add llms.txt (it is still a proposal, with no guaranteed effect). A coding agent working in your repo → write AGENTS.md/CLAUDE.md. A body of structured knowledge an agent uses repeatedly → put it in OKF. The answer is often "all of them," but do not use one as if it were another.
"Markdown for AI" is not one thing; it is three layers. Once you know who each one talks to and when it is read, the real question is no longer which to pick. It is whether you have covered all three.